1 Min Q&A – Data Representation & Normalised Floating-Point

Q: Why does floating-point binary struggle to store clean decimals like 0.1?

A: Binary counts in negative powers of 2 (halves, quarters, eighths). Fractions like 0.1 turn into infinitely recurring binary fractions, forcing floating-point systems to round off and introduce tiny precision errors.

#CIE
Theory & Architecture (Paper 1 & 3)
Data Representation & Normalised Floating-Point

1 Min Q&A – CPU & Von Neumann Architecture

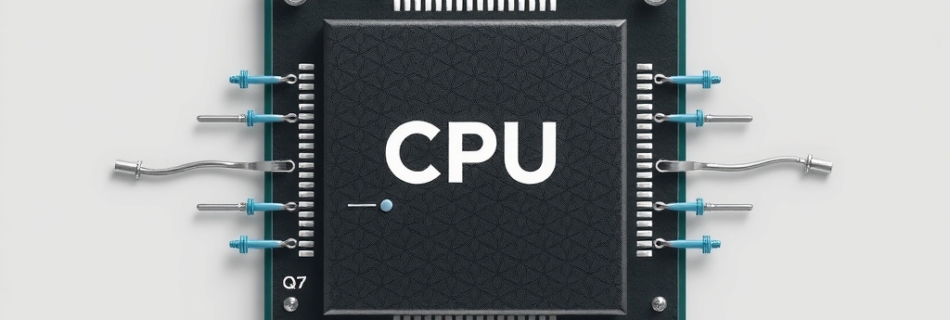
Q: What are CPU registers and why do we need them?

A: Registers are micro-sized, insanely fast memory slots sitting directly on the chip. The Program Counter holds the next address, MAR targets memory locations, MDR holds data payloads, and the Accumulator keeps running math totals.

#OCR
1.1 Systems Architecture
CPU & Von Neumann Architecture

Google will now allow users to remove visible watermark from its AI generations

Is removing visible AI watermarks a step forward for creative freedom, or a dangerous slide into widespread digital deception?

Google now allows users to toggle off visible watermarks on its AI-generated media, though invisible benchmarks—such as metadata embedded to verify synthetic origins—remain active behind the scenes.

From an IT and tech-ethics perspective, this update neatly balances aesthetic utility with backend accountability. However, relying solely on invisible tracking challenges the *Principle of Explicit Transparency* in AI governance. If everyday users cannot visually detect synthetic content, are we over-relying on background verification tools that the general public rarely utilizes? By removing the immediate visual cue, we risk shifting implicit trust entirely onto black-box algorithms rather than fostering human critical thinking.

As IT professionals and educators, we must ask: Does hiding visible labels undermine broader digital literacy, or is robust invisible tracking truly enough to safeguard information integrity in the generative AI era? What are your thoughts?

—

移除 AI 可視水印,究竟是賦予創作自由,還是推開數位信任危機的大門?

Google 最新政策允許使用者關閉 AI 生成內容的可視水印,但背景中用於識別 AI 檔案的「隱形標記」與驗證基準仍會持續保留。

從資訊科技與科技倫理的角度來看,此舉企圖在視覺美學與責任歸屬之間取得平衡。然而,僅依賴隱形追蹤技術,實質上挑戰了 AI 治理中的「顯性透明度原則」(Principle of Explicit Transparency)。當一般大眾無法再透過肉眼辨識合成媒體時,我們是否過度依賴大眾根本不會主動使用的後台檢測工具?這是否意味著我們正將「信任機制」完全讓渡給平台演算法,而非建立大眾的判讀能力?

作為 IT 專業人士與教育者,我們不得不思考:隱藏可視標籤是否會削弱社會整體的數位素養?隱形追蹤技術真的足以捍衛生成式 AI 時代的資訊真實性嗎?歡迎在下方分享你的見解!

#AIEthics #GoogleAI #DigitalTrust #ITProTutor

Source: TechCrunch

https://techcrunch.com/2026/08/14/google-will-now-allow-users-to-remove-visible-watermark-from-its-ai-generations/

This scientist is helping build a missing map of childhood

Ever wondered if the data models driving healthcare are missing half the human story?

In bio-data analytics, training models on biased datasets leads to fundamentally flawed outputs. When the ambitious Human Cell Atlas project launched to map every cell in the human body, computational biologist Deanne Taylor identified a critical systemic gap: the baseline data almost entirely omitted pediatric gene expression. Children are not simply “scaled-down adults”; their cellular architecture and genetic expression undergo unique dynamic shifts. Taylor’s work in building a dedicated pediatric cell atlas addresses this missing infrastructure, ensuring biomedical data science truly reflects human development.

From an IT and data governance perspective, this highlights the profound danger of **Representational Bias** in algorithms. In machine learning, if your training pipeline ignores a demographic’s baseline parameters, the resulting predictive models fail when deployed in edge-case or specialized scenarios—in this case, pediatric care. Are we unknowingly building biological information systems that discriminate against younger populations due to incomplete foundational data? How can data architects ensure equitable data sampling before scaling AI-driven medical solutions?

—

你是否想過,我們用來訓練醫療 AI 的數據,可能根本遺漏了人類生命的關鍵章節?

在生物資訊學中,數據偏差會直接導致系統性的推論錯誤。當「人類細胞圖譜」(Human Cell Atlas)計畫啟動時,計算生物學家 Deanne Taylor 發現了一個致命漏洞:基礎數據庫幾乎完全排除了兒童的基因表達。兒童並非「縮小版的大人」,其細胞結構與基因調控具有獨特的動態發展脈絡。Taylor 致力於建構缺失的「兒童細胞圖譜」,正是為了補齊這項數據基礎設施,確保生物醫學數據科學能精準反映整體人類發育。

從資訊系統與機器學習的角度來看,這觸及了著名的**「代表性偏差」(Representational Bias)**與資料治理議題。如果訓練模型時缺乏特定族群的基線數據,演算法在診斷或預測特定情境(如兒童醫療)時將產生嚴重失真。我們在推動生醫資訊數位轉型時,是否正無意間構建了一個對兒童失效的演算法系統?數據架構師又該如何在模型擴展之前,從源頭確保數據抽樣的完整性?

#Bioinformatics #DataEthics #PediatricHealth #ITProTutor

Source: MIT Technology Review

https://www.technologyreview.com/2026/08/14/1141354/deanne-taylor-gene-expression-children/

1 Min Q&A – CPU & Von Neumann Architecture

Q: What is the Fetch-Decode-Execute cycle in plain English?

A: It is the relentless three-step routine of a processor. First, it fetches an instruction from RAM. Next, it decodes what the instruction demands. Finally, it executes the instruction and repeats the process billions of times before your tea gets cold.

#OCR
1.1 Systems Architecture
CPU & Von Neumann Architecture

‘I worked really hard and it paid off’: Elation, nerves and proud parents as students get results

Is the traditional academic pipeline still the ultimate benchmark for success in our fast-evolving digital era?

Today’s exam results highlight extraordinary human resilience—from a Ukrainian refugee overcoming severe language barriers to a frontline firefighter balancing public service with academic rigor. These stories remind us that true learning is an iterative, lifelong debugging process rather than a single high-stakes deployment.

As an IT tutor, I view these achievements through the lens of Carol Dweck’s *Growth Mindset* theory and the tech industry’s ongoing shift from rigid credentialism to practical competency. While we celebrate these students’ grit, their unconventional paths raise a critical question: Does our current standardized assessment model truly measure computational thinking and real-world adaptability, or merely test mechanical compliance? In an age where AI can automate rote knowledge instantly, should education pivot toward continuous skill validation and project-based learning instead of high-pressure final exams?

What are your thoughts—is it time to refactor our global education architecture?

—

在快速迭代的數位時代,傳統的標準化考試依然是衡量人才的唯一鐵律嗎?

今日公布的放榜結果展現了極致的學習韌性——從克服語言障礙的烏克蘭難民,到兼顧第一線救災使命與學業的消防員。這些故事告訴我們,真正的學習是一個持續「除錯(Debugging)」與動態優化的過程,而非單一次的高風險部署。

從 IT 教育者與系統思維的角度來看,這完美契合了 Carol Dweck 的「成長型心態(Growth Mindset)」理論,也反映出科技產業正從「文憑主義」轉向「實戰技能」的趨勢。在為這些學生喝采的同時,我們也必須深刻反思:現行的統一評量機制,究竟是在篩選解決問題的敏捷度,還是在測試機械式的抗壓性?當 AI 已能瞬間處理記憶型知識,我們的教育架構是否該轉向以專案為導向的持續性能力驗證?

你認為未來的教育體系該如何重構?歡迎在下方留言討論!

#ExamResults #GrowthMindset #FutureOfEducation #ITProTutor

Source: BBC News

https://www.bbc.co.uk/news/articles/c4gd47j24wyo?at_medium=RSS&at_campaign=rss

Nvidia’s new $500B plan is risky but brilliant, especially for aging GPUs

Is Nvidia single-handedly engineering a financial safety net to redefine hardware depreciation in the AI era? Nvidia’s ambitious $500B strategy aims to stabilize GPU residual values by incentivizing a new class of financiers to fund ongoing AI infrastructure expansions. As an IT tutor, I find this convergence of deep tech and high finance fascinating.

Traditionally, technology hardware follows a strict dynamic dictated by Moore’s Law and economic asset depreciation: as newer architectures emerge, older silicon undergoes rapid devaluation. By attempting to artificially preserve the asset value of legacy GPUs, Nvidia is effectively “financializing” compute capacity. But this raises critical questions: Is Nvidia brilliantly de-risking the AI infrastructure bubble, or is it creating a moral hazard by over-leveraging aging silicon against faster, more energy-efficient microarchitectures? When real-world AI workloads demand exponential efficiency gains, can financial ingenuity truly substitute for raw hardware advances? What are your thoughts—brilliant ecosystem lock-in or an unsustainable financial shield?

NVIDIA 是否正在一手打造一套金融防護網,徹底重塑 AI 時代下的硬體折舊法則?NVIDIA 提出了一項高達 5,000 億美元的宏偉計劃,旨在吸引新型金融投資者持續投入 AI 基礎建設,進而鎖定並維護舊款 GPU 的殘餘價值。作為一名 IT 導師,這種深厚科技與高等金融的深度結合令人深思。

傳統上,資訊硬體遵循摩爾定律(Moore’s Law)與資產快速折舊的規律:隨著新架構問世,舊晶片價值必然暴跌。NVIDIA 試圖人工維持舊晶片資產價值的做法,實質上是將「算力金融化」。但這引發了深層的技術與經濟疑問:NVIDIA 究竟是在巧妙地降低 AI 基礎建設的泡沫風險,還是在面對下一代高能效架構時,因過度槓桿化舊硬體而製造了道德風險(Moral Hazard)?當軟體需求遠超硬體極限,金融工程真能替代物理晶片的效能提升嗎?這究竟是高明的生態系鎖定,還是難以持續的金融護城河?歡迎留下你的見解!

#Nvidia #AIFinance #HardwareDepreciation #ITProTutor
Source: TechCrunch

https://techcrunch.com/2026/08/13/nvidias-new-500b-plan-is-risky-but-brilliant-especially-for-aging-gpus/

What’s behind this summer’s heat, and why 2027 could be worse

Are our predictive algorithms failing us, or are we witnessing a critical system-level overflow in the planet’s climate architecture?

Recent records show Europe, the United States, and Asia enduring unprecedented heatwaves, with models indicating that upcoming El Niño dynamics could push extreme temperatures even higher. Treating Earth as a massive distributed system, we are currently observing severe hardware resource contention and thermal throttling driven by greenhouse gas inputs.

Applying Chaos Theory and System Dynamics, minor thermal anomalies in ocean currents act like unhandled micro-exceptions in complex code, cascading into global operational failures. As IT professionals building next-generation infrastructure, this raises vital questions: Are we merely logging climate data, or are we engineering system resiliency for high-temperature operational environments? When our primary physical layer—the planet—fails its thermal specification tests, how must our data centers, algorithmic models, and edge devices evolve to maintain uptime? Share your technical perspectives below.

—

我們的預測演算法是否正面臨系統溢位(System Overflow)?全球氣候硬體已然進入極端過熱狀態!

最新數據顯示北半球正遭遇史無前例的酷熱考驗,歐美及亞洲多地氣溫刷新歷史紀錄,而聖嬰現象更可能將危機推向新高峰。從資訊系統架構的角度來看,這意味著地球正因溫室氣體過載而面臨嚴重的資源爭用與熱節流(Thermal Throttling)。

引用「系統動力學」與「混沌理論」,海洋溫度的微小擾動如同程式碼中未處理的異常(Exceptions),最終引發全球級的連鎖系統崩潰。作為建構下一代基礎設施的科技從業人員,我們必須深思:我們只是將氣候變遷視為單純的 Log 記錄,還是有在積極規劃高溫環境下的系統韌性?當底層硬體——地球本身——無法通過散熱測試時,我們的資料中心與演算法該如何調適?歡迎在下方留言討論!

#ClimateTech #SystemsThinking #DataAnalytics #ITProTutor

Source: MIT Technology Review

https://www.technologyreview.com/2026/08/13/1141788/summer-heat-el-nino/

London pulls further ahead as A-level regional divide for top grades hits record – latest news

Are we witnessing a structural bug in our educational pipeline, or a feature of entrenched systemic inequality?

The latest A-level results reveal a record-breaking disparity in top grades between London and the North East of England. Concurrently, international undergraduate acceptances have surged by 2%—driven largely by a rise in Chinese applicants—while debates surrounding student loan fairness continue to spark concern.

From a systems engineering perspective, education should act as an open, meritocratic network that maximizes human capital regardless of location. However, this widening geographic divide clearly illustrates the **Matthew Effect** (“the rich get richer”), where existing resource advantages compound over time. If access to high-tier learning infrastructure, digital tools, and funding remains centralized, can standardized assessments ever truly be objective? Furthermore, as universities increasingly optimize for international market demand to secure revenue, how can policy framework designers re-architect the system to preserve local equity without compromising global competitiveness?

Is it time to re-engineer educational assessment using context-aware, data-driven algorithms, or must we overhaul the underlying infrastructure altogether? Share your insights below!

***

我們是在目睹教育系統的「程式錯誤」(Bug),還是階級不平等的「預設功能」?

最新的 A-level 考試結果顯示,倫敦與英格蘭東北部之間取得頂尖成績的區域差距已創下歷史新高。與此同時,國際本科生錄取量增長了 2%(主要由中國申請者驅動),而關於學生貸款公平性的討論亦再度引發關註。

從系統工程與 IT 架構的角度來看,教育本應是一個開放且兼具功績主義(Meritocracy)的賦能網路。然而,當前的區域失衡顯然印證了「馬太效應」(Matthew Effect)——資源優勢在特定地區不斷累加。當優質教學資源與數位基礎設施分布不均時,單一的標準化測驗是否還能客觀反映學生的真實潛力?此外,當高等教育體系為了收益極大化而向國際市場傾斜時,政策制定者又該如何重新設計架構,以兼顧本地教育公平與全球競爭力?

我們是否需要引入具備「情境感知」(Context-aware)的數據驅動機制來重構現有體系?歡迎在下方留言分享你的看法!

#ALevelResults #EducationEquity #EdTech #ITProTutor
Source: The Guardian

https://www.theguardian.com/education/live/2026/aug/13/a-level-results-universities-clearing-schools-college-sixth-forms-latest-news-updates